The Serverless Resource Ceiling That Caps What an Agent Can Actually Do
Serverless resource caps make certain agent capabilities impossible to build.
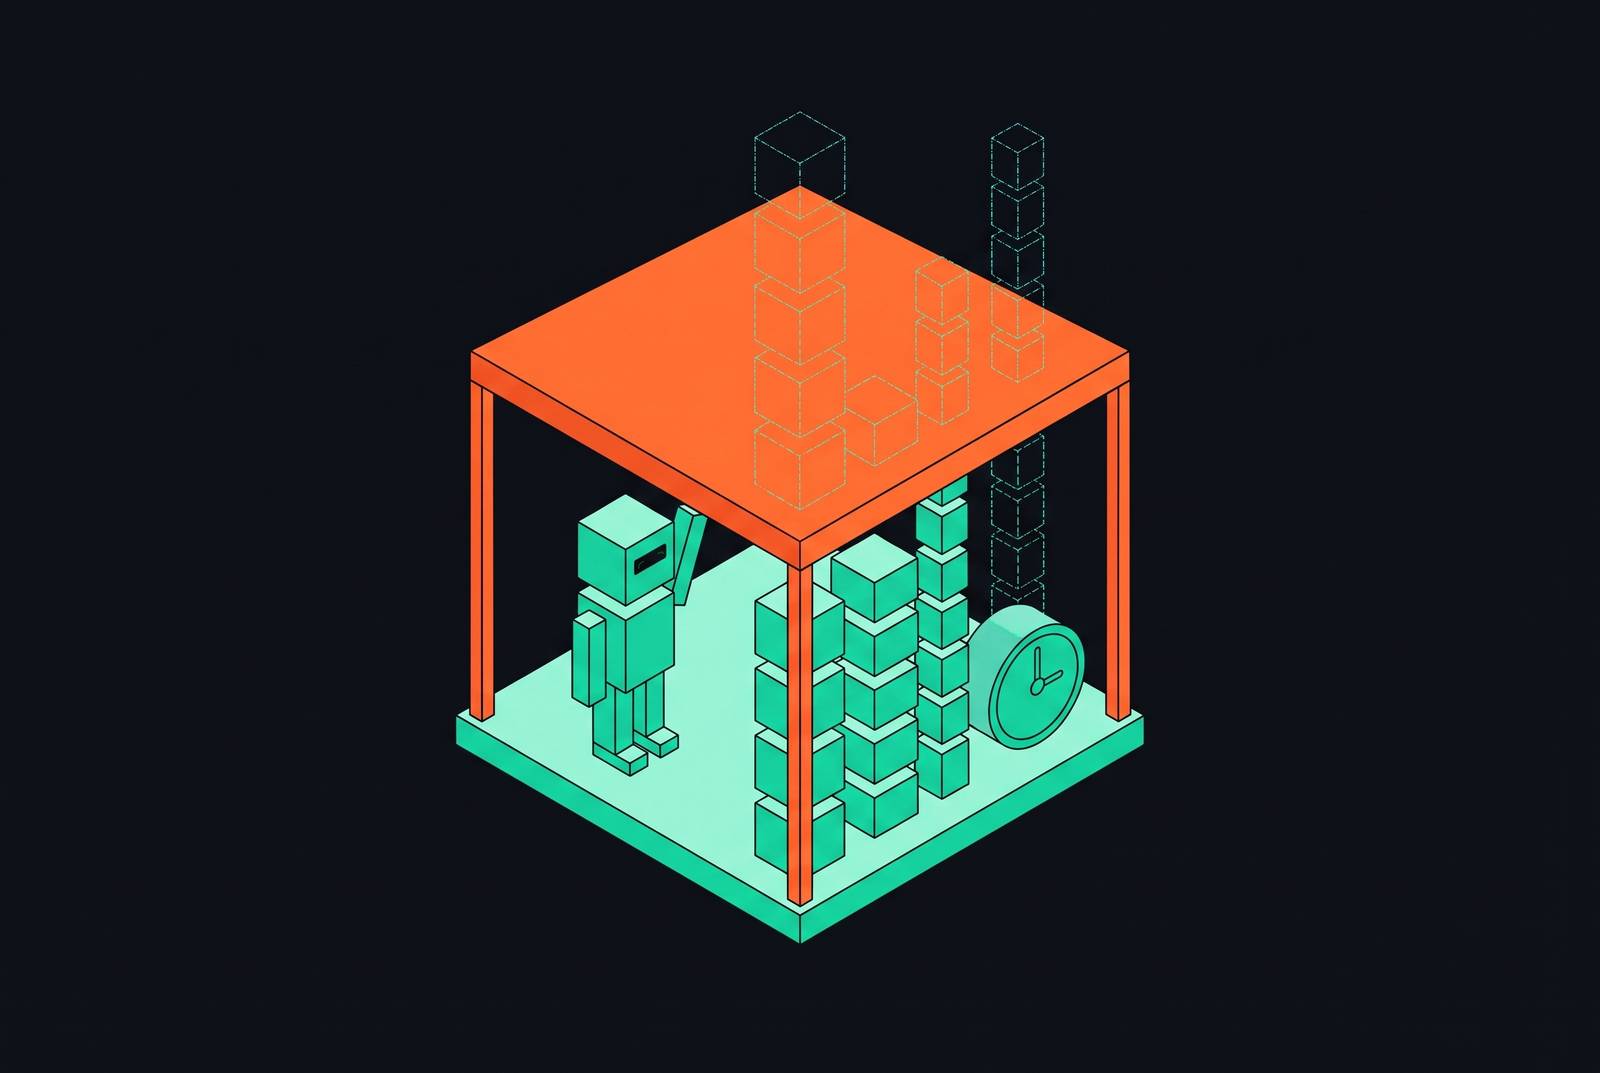
Serverless resource limits determine which agent capabilities are buildable and how much they cost. Persistent AI agent infrastructure keeps a working environment through long-running tasks, tool calls, and approval waits, while serverless functions do not. For agents that need substantial dependencies, local inference, and durable context, the appropriate model is a persistent execution environment with snapshot-restore.
Why serverless platforms were not designed for what agents actually do
Serverless execution is built for short, stateless, bursty work triggered by events. A function starts, handles its event, terminates, and bills per invocation. The platform treats the interval between invocations as time when no execution environment needs to exist. That is a useful model for discrete operations. It is a poor match for work whose next step depends on preserving the environment of the previous one.
An agent is a loop. It reasons, calls a tool, reads the result, and reasons again, spending much of its wall-clock time waiting on models, APIs, or human approvers. Lyzr’s runtime comparison identifies three properties that decide the runtime fit, namely how long a task runs, how much state it retains, and what it waits on. A two-second classification step fit serverless, while the multi-step investigation encountered problems with duration, state, and waiting simultaneously. The mismatch arose from the shape of the work.
Why long-running AI agents fail on serverless timeouts
AWS Lambda imposes a maximum execution duration of 15 minutes. That limit filters capabilities before questions of throughput or cost arise, because a workflow that exceeds it cannot finish within one invocation. Waiting consumes the available wall-clock window too. Cloudflare Workers makes a different distinction, allowing unlimited wall-clock time while capping CPU time. These are separate constraints, so an architecture must account for whether its work exhausts elapsed time, active computation, or both.
A research workflow shows how easily elapsed time accumulates. It takes 2–3 minutes to search multiple data sources, 3–5 minutes to analyze the findings, 5–8 minutes to generate a report, and 1–2 minutes to format it. The total is 11–18 minutes. At the upper end, the total is above Lambda’s maximum, though each stage on its own is below it. Without separately persisted progress, a timeout leaves no completed output, and retries can multiply LLM spending by repeating work already performed.
Human approval exposes a harder boundary than variable processing time. An agent working through a legal document may need to stop for an approver before proceeding. That wait belongs to the workflow, even when it involves no computation. Lyzr’s comparison notes that a serverless function “can't wait days for an approver”.
The bundle size ceiling and the ML dependency problem
AWS Lambda limits ZIP deployment packages to 50 MB compressed and 250 MB uncompressed. Vercel Functions has a 250 MB uncompressed limit including layers, while Cloudflare Workers has a 64 MiB uncompressed limit on both free and paid plans. These limits constrain the tools an agent can bring into its execution environment. They are not simply upload inconveniences. An agent cannot run an analysis locally if the dependencies it needs are too large for the supported deployment format.
Scikit-learn, pandas, numpy, and scipy together routinely exceed 250 MB. A vector database client and an LLM SDK make the package even larger, before any model weights are added. In a documented e-commerce recommendation-engine example, scikit-learn and pandas alone made the deployment package too large for Lambda’s limit.
Container images provide a real exception to the ZIP restriction. Lambda accepts images up to 10 GB, allowing dependencies that would otherwise be excluded from that deployment path. The exception changes the operational bargain, however. The developer takes on a more complex deployment process and manages containers rather than relying on the simpler function-package model. Larger packaging capacity also does not resolve execution duration or the time needed to initialize those dependencies.
Cold starts as a hidden capability tax on agent responsiveness
“Pay only for what you use” is attractive when an agent spends much of its time idle. Under that promise, an inactive agent should incur no running-compute cost until work arrives. The difficulty appears when that work requires a large model to be ready immediately. Initialization is not instantaneous or free of consequences. A Lambda cold start with a large model can take 30–60 seconds before the agent starts work on its task.
For a user-facing interaction that expects a sub-second response, initialization alone can consume far more time than the interaction permits. This is a capability constraint as well as a latency problem. An agent that can eventually perform a task may still be unsuitable for an interface that requires an immediate response. Moving large dependencies into a container image does not remove the need to load them. Packaging and responsiveness remain distinct requirements.
Provisioned concurrency addresses cold starts by keeping execution environments warm. It therefore adds a continuous baseline cost whether agents are active or not. Letting environments go cold preserves the idle-cost advantage while delaying the next response. Keeping them ready restores responsiveness by charging for capacity during periods when the agent has no work.
The stateless model and why it makes multi-step agent context structurally fragile
A serverless invocation is not a durable home for an agent’s working context. Files, browser sessions, credentials held in memory, caches, and runtime-installed packages cannot be treated as reliably available across invocation boundaries. The workflow must reconstruct what the next step needs. Persisting selected data outside the function addresses part of that problem, but it does not preserve the working process itself. The boundary becomes an explicit coordination task.
Using DynamoDB or S3 requires serializing state before one step ends and deserializing it when the next begins. Each transfer adds latency, implementation work, and another opportunity for failure. Lyzr’s refund investigation illustrates the consequence of splitting work to fit execution limits. The team chained functions and saved state after each step, until “a simple function was becoming a fragile distributed system”. A workaround for duration had created a separate state-management problem.
Human-in-the-loop pauses intensify that burden because active workflows must remain securely recoverable for potentially long periods without consuming running resources. AWS Lambda durable functions, announced December 2025, provide a significant mitigation by allowing an execution to suspend for up to a year without compute charges during suspension. That changes what can be built on Lambda. It does not make the base invocation model stateful. Durable execution supplies an additional layer for waiting and resumption that a short-lived function does not provide on its own.
GPU access inside serverless and why it caps agent inference capability
AWS Lambda’s standard offering exposes no GPU resource type, CUDA drivers, or GPU billing dimension, as described through late 2025. For an agent that requires GPU-backed local inference, this is an absence rather than a setting to tune. Increasing the execution timeout cannot supply an accelerator. Neither can changing the package format. The required resource must exist in the execution environment before the workload can use it.
Serverless GPU offerings are a different category from standard Lambda functions, but their access model introduces other constraints. Queued access and narrow instance choices differ from direct, reserved access on dedicated infrastructure. For real-time agents, availability affects whether inference can start when needed. At serious inference volume, the economic comparison also shifts toward dedicated resources. A serverless product must offer a GPU with an access and pricing model that fit the agent’s workload.
Hosting a model locally also takes enough memory. Models requiring 8 GB+ RAM and multi-billion-parameter weights make that requirement difficult to reconcile with constrained function environments. External model APIs avoid loading those weights locally. But they add network latency and per-token costs to the reasoning loop, which then also depends on third-party availability. They are an alternative execution path.
How the limits interact and why one workload can hit them together
The execution-time, package-size, and cold-start constraints tend to converge on the same workloads. A research agent that searches, analyzes, and writes may need more than 15 minutes, ML libraries exceeding 250 MB, and a substantial initialization phase. It also needs context across reasoning steps and potentially GPU-accelerated inference. Fixing the first deployment error still leaves the other limits on how the task can run.
For a coding agent, cloning a repository adds startup time, and multi-pass analysis needs enough execution time to inspect, modify, and test code over and over. Those attempts depend on a persistent filesystem. Keeping test runners and package caches between attempts saves the work of rebuilding them at each boundary. ETL and content-generation agents, including PDF creation and media transcoding, add demands for fast, scalable local storage while often exceeding execution-duration constraints.
Chained functions reduce the duration of each invocation but increase state-transfer overhead. Container images allow larger packages than the ZIP package restriction does, but they make deployment more complex and still have initialization costs. Keeping those environments warm then weakens the economic case for idle agents. Taken together, these accommodations amount to rebuilding persistent-process infrastructure inside a system whose base abstraction deliberately avoids providing it.
What the architecture must provide instead, and why microVM isolation with snapshot-restore is the right primitive
The alternative architecture follows directly from the constraints. An agent needs a long-lived execution environment without a function-style deadline, a real filesystem with package installation privileges, and continuity across tool calls and approval waits. Dependencies should remain installed between sessions. Local inference also requires infrastructure that can provide direct GPU access at reserved pricing where the workload calls for it. These are properties of the whole architecture.
A persistent microVM per agent supplies an isolated working environment, while snapshot-restore makes suspension part of its normal lifecycle. Instead of rebuilding the process after each pause, the platform preserves its disk and memory state for resumption. Firecracker’s snapshot restore achieves roughly 28 ms compared with well over a second for a cold boot. Execution latency inside the restored VM runs in single-digit milliseconds. Restoring the environment changes startup from loading a kernel and rebuilding context into thawing saved memory.
That lifecycle also addresses the cost of waiting. Most agents are idle most of the time, so keeping every environment continuously active would incur the same continuous baseline cost as keeping functions warm. A snapshot-restore scheduler suspends idle agents and restores them when work resumes. During suspension, the agent pays for storage rather than compute, allowing idle cost to trend toward zero without discarding its working state. Persistence describes continuity here.
AWS Bedrock AgentCore adopted the microVM model for production multi-tenant agents, giving each user session isolated CPU, memory, and filesystem resources. MicroVM isolation also introduces hardware-enforced kernel separation instead of the shared host kernel used by containers. That creates a stronger boundary between neighboring environments. Copy-on-write forking adds another useful property by cheaply branching a running VM’s memory and disk. An agent can try five fixes from the same starting state and keep the one that passes without repeated cold initialization or full duplicate provisioning.
Each user gets a separate kernel, persistent filesystem, and installed tooling, while the platform packs many VMs onto each host. Snapshots allow an environment to pause overnight and resume quickly without reserving active compute throughout the wait. The architectural criterion is continuity at storage-like idle cost. That is the distinction between infrastructure that merely executes an agent’s next function and infrastructure that preserves the agent’s ability to finish its work.